 NexAIX-官方博客
In 2026, whether you are building a complex multi-Agent system or simply migrating your existing application to a more powerful large model, you may have realized: being able to connect to an API is just the beginning; keeping it stable in production is the real test.
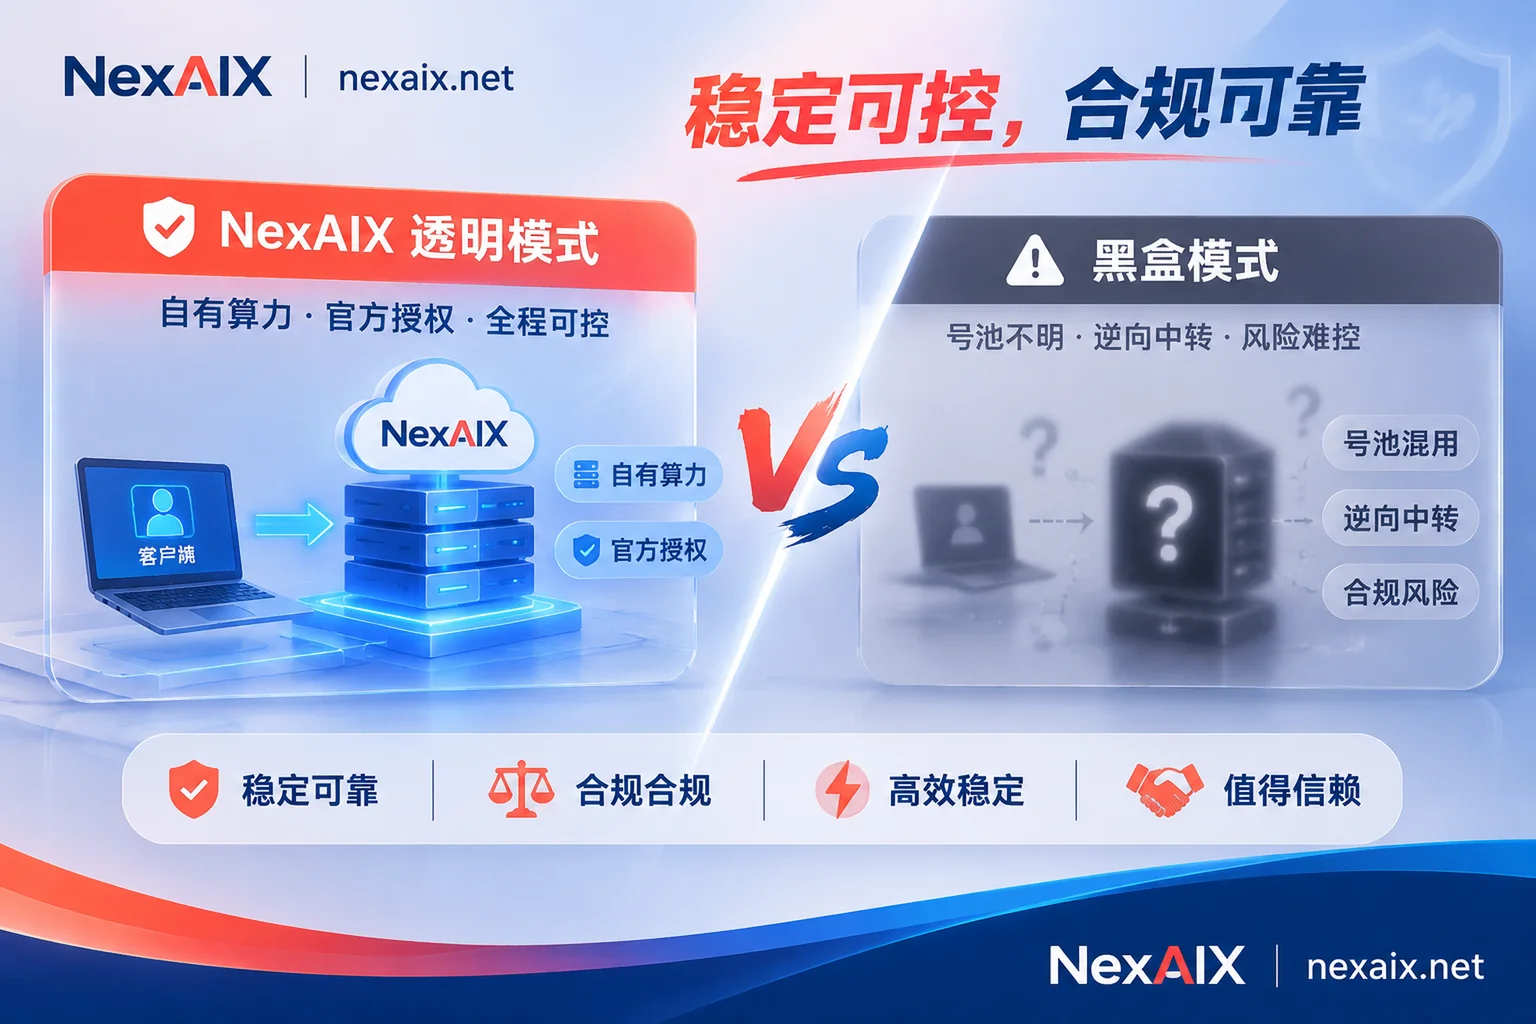
The market is flooded with various API relay services claiming to be "OpenAI-compatible," but many developers encounter implicit model swapping, degraded inference accuracy, or even uncontrollable data retention risks after integration. For technical leaders in production environments, building business on a "black box" is like building a castle on sand.
Say Goodbye to the "Black Box": NexAIX's Transparent Governance Path
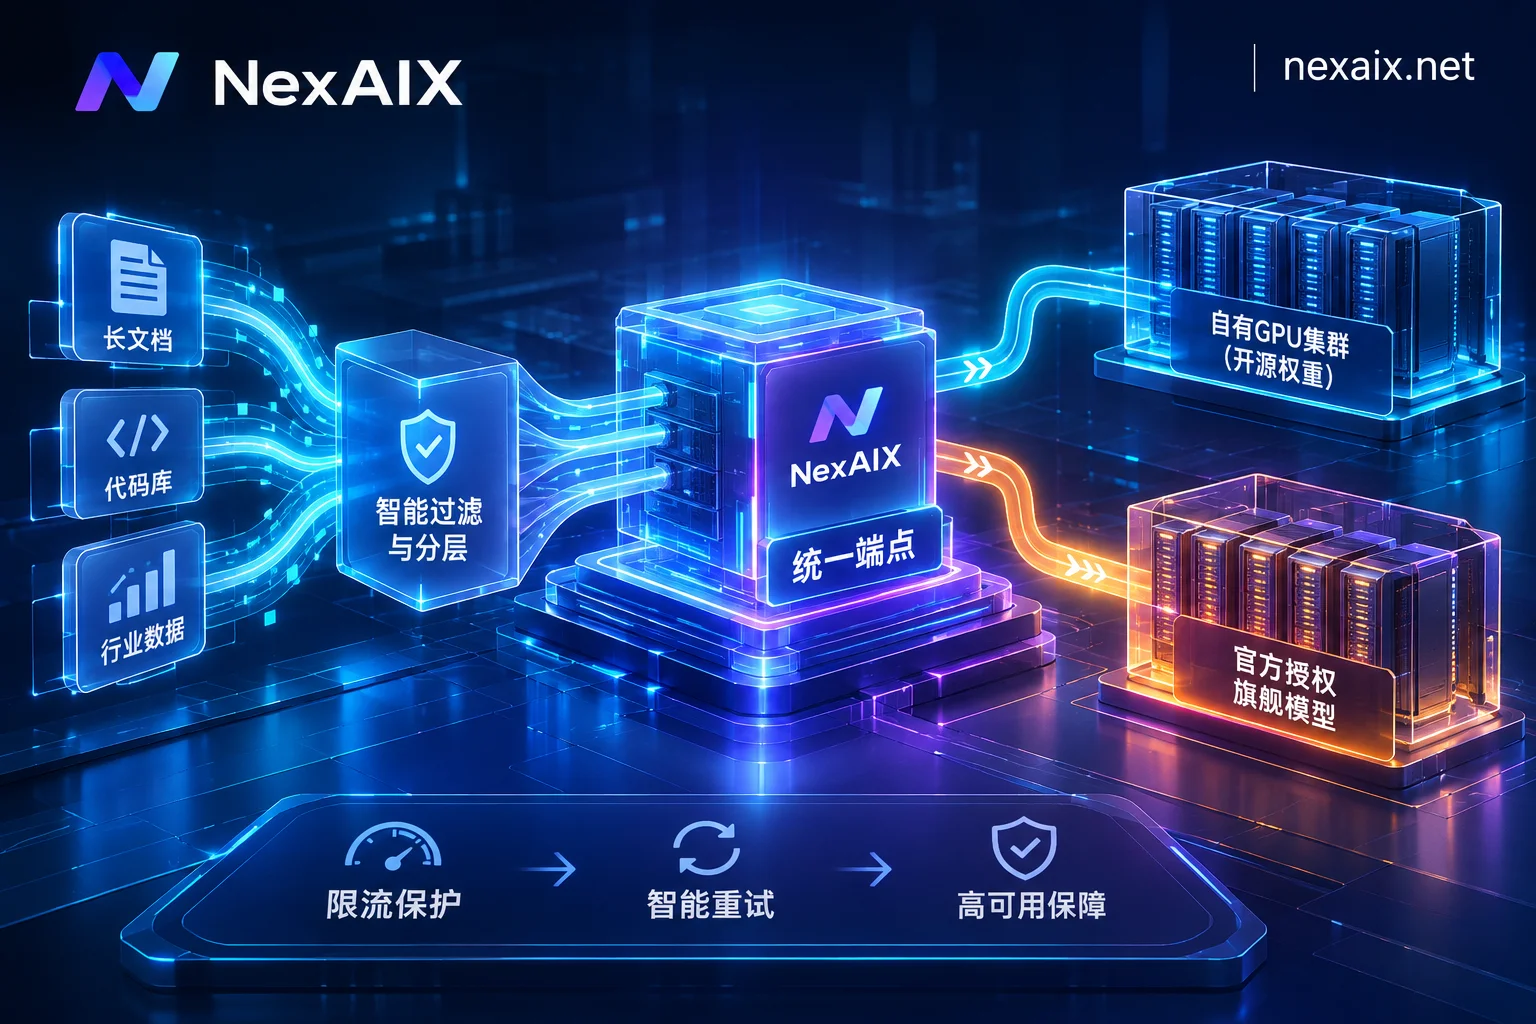
NexAIX (nexaix.net) has a very clear positioning: we are not simple API resellers, but your partner providing highly controllable infrastructure. We offer two clear supply methods, rejecting chaotic account pools and reverse-engineered solutions:
- Self-owned Compute Deployment (Open-Source Weights): For officially released open-source models, we deploy directly on our self-built and self-leased GPU clusters, without reselling any third-party quotas. We clearly label the model's context, inference precision (BF16/FP8/MXFP4, etc.), and license, ensuring you get results from the original weight inference.
- Official Authorized Channels (Closed-Source): For closed-source models like Claude, GPT-5.6, Gemini, etc., we use official commercial licenses from the vendors. Contracts, invoices, and auditability are all in place, fully meeting production-grade compliance requirements.
You can always check our Transparency Statement to understand the essential differences between us and common relay services on the market.
One Key, Unlock the Entire Model Ecosystem
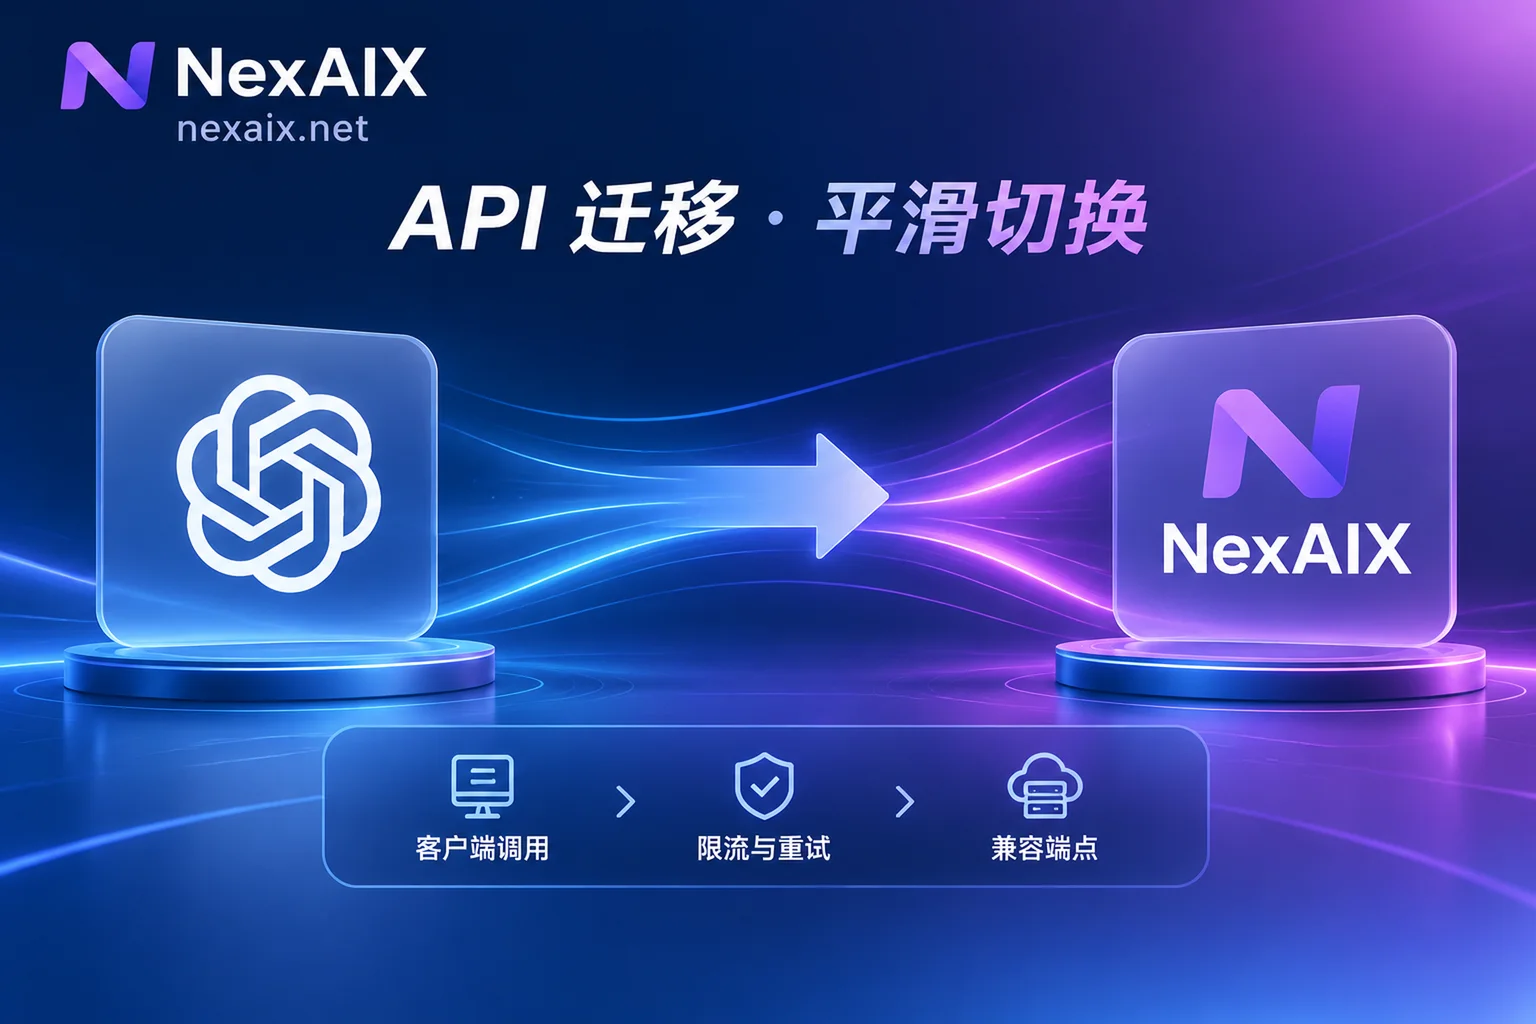
For development teams, efficiency is crucial. NexAIX strictly follows the OpenAI Chat Completions specification. This means that if your project is already using the OpenAI SDK, in most cases, you only need to change base_url to https://api.nexaix.net/v1 and replace it with your NexAIX Key.
Whether it's LangChain, LlamaIndex, Dify, NextChat, or Cline, any client that supports custom OpenAI base_url can seamlessly integrate. View integration guide.
Our Commitment to "No Downgrades"
We understand that in production, the last thing you want is to be "played." NexAIX solemnly promises:
- No model swapping: The
modelfield in the response body indicates the actually executed model. - No precision reduction: Maintain the model's original inference capability.
- No truncation: Respect your context and token settings to the maximum extent.
- No hidden interference: No hidden system prompts are injected.
We provide four self-check methods, encouraging developers to "stress test" and "review" our API at any time.
Compliance Built for Agents
Data privacy is the lifeline for enterprises using large models. NexAIX adopts a minimalist processing strategy on the server side: Prompts and Completions are forwarded only in memory, released immediately after the request ends, not written to disk, not used for training, and not shared with third parties.
We support isolated billing and permissions by Key. Each Key has independent quota configuration and can be revoked at any time if leaked. For enterprises with extremely high compliance requirements, we also offer dedicated resource pools and private deployment solutions (welcome to contact [email protected] for consultation).
Ready to deploy your Agent on transparent, stable infrastructure?
Register with NexAIX now, claim your test quota, and start your production-grade AI journey.
Want to learn more practical tips to avoid pitfalls? Welcome to read our in-depth guides: